
WeKnora
AITencent's open-source LLM knowledge framework turning documents into a RAG-queryable, agent-reasoned, self-maintaining wiki.
WeKnora
Tencent's open-source LLM knowledge framework turning documents into a RAG-queryable, agent-reasoned, self-maintaining wiki.
About WeKnora
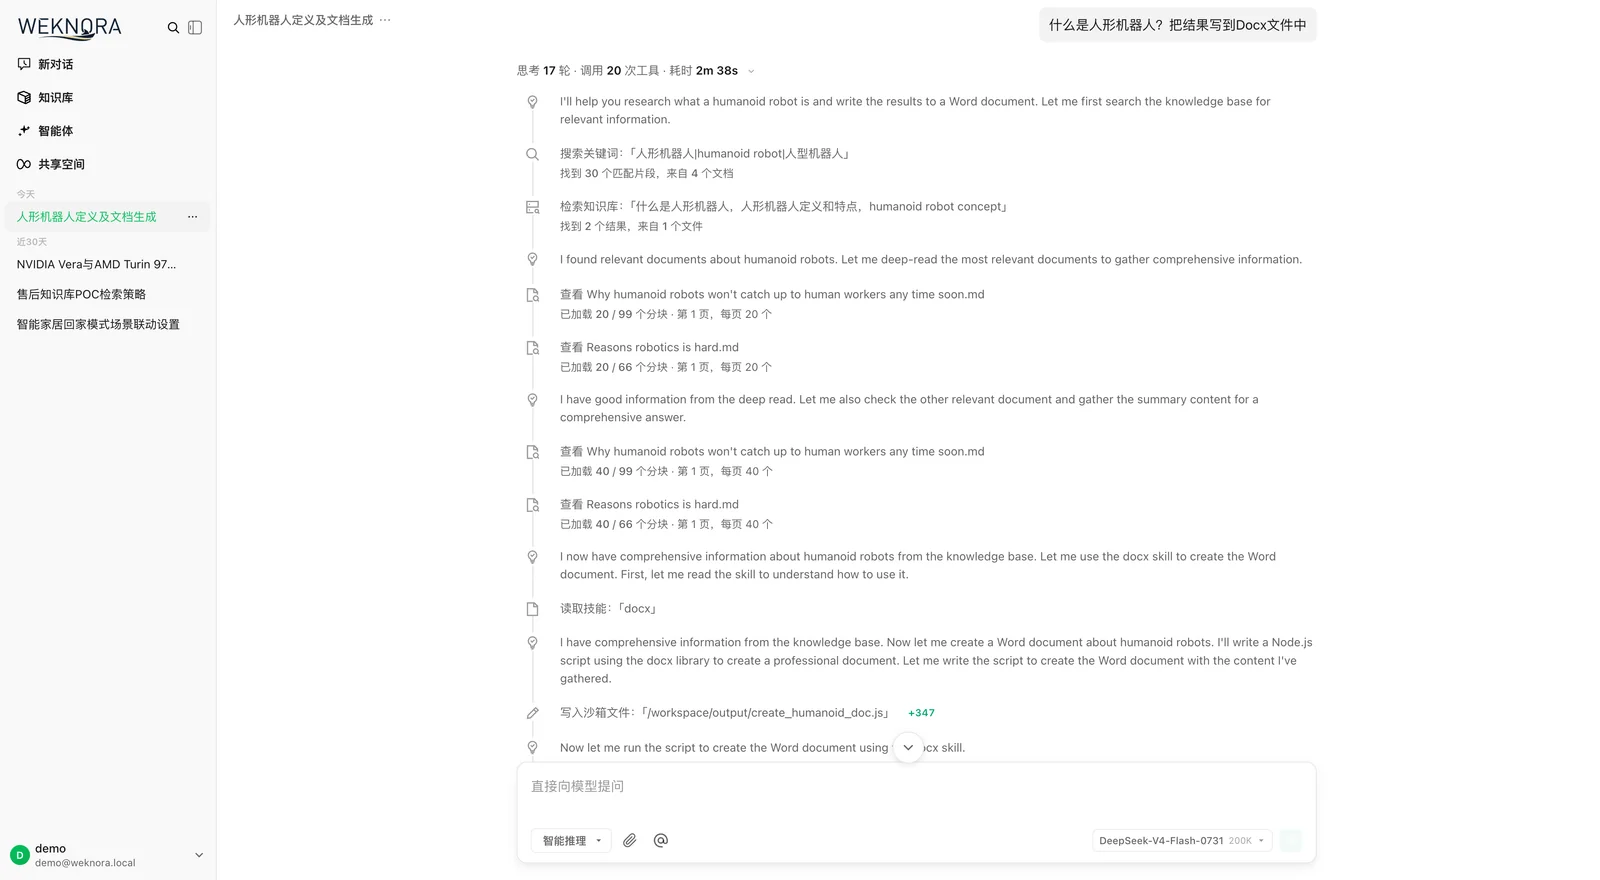
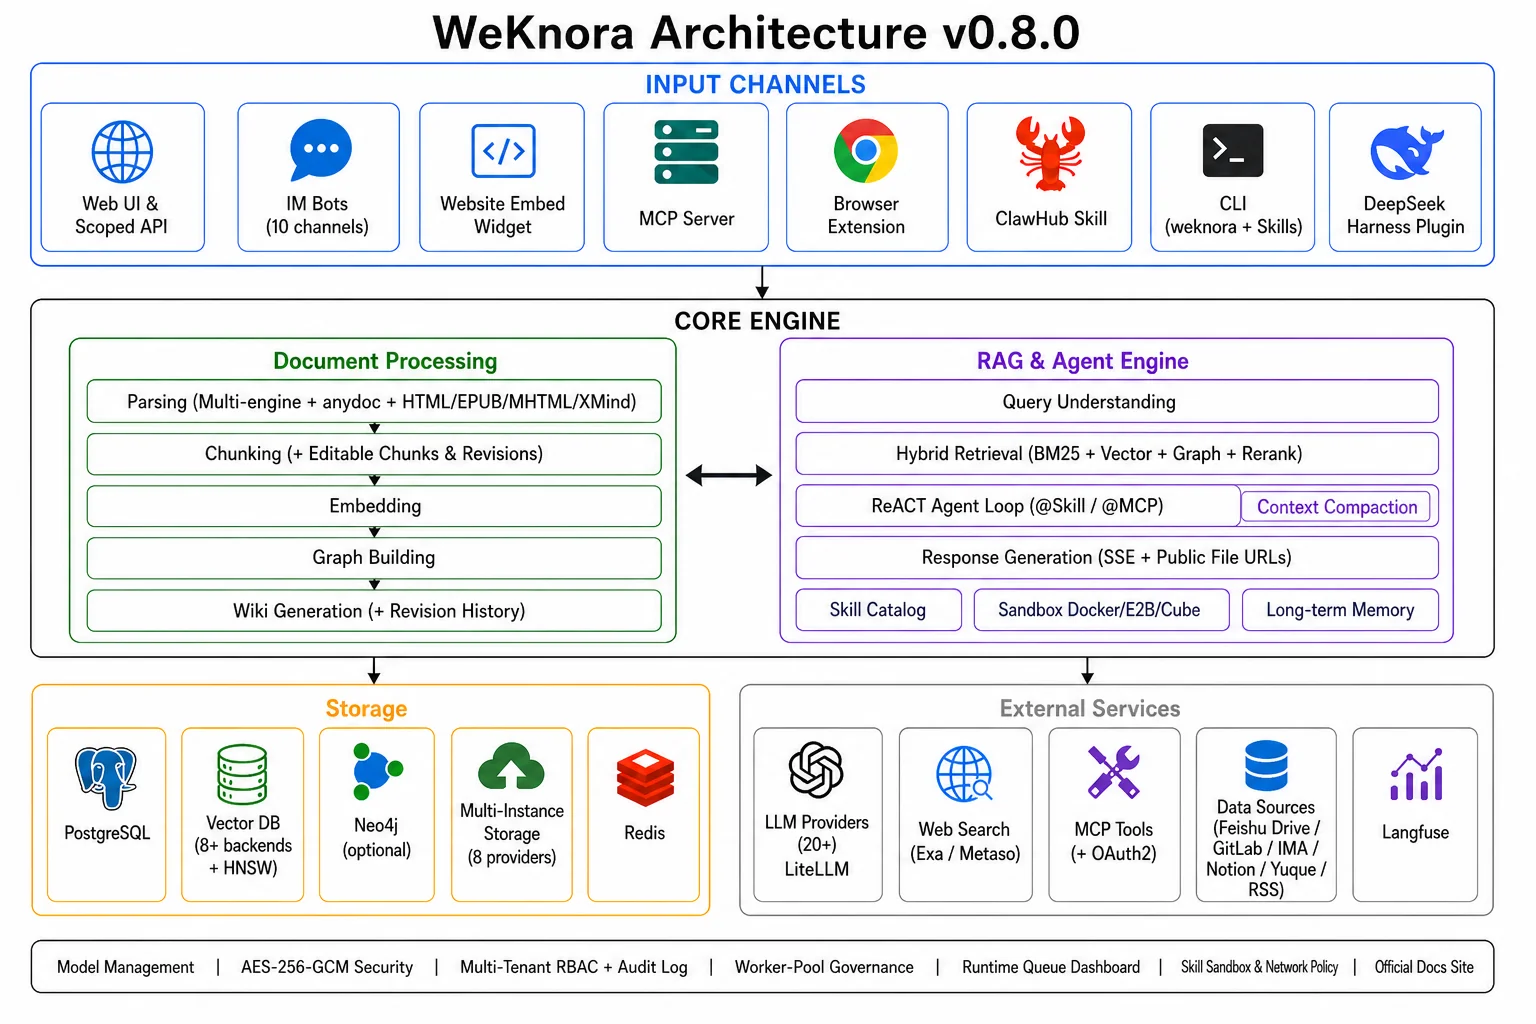
WeKnora is an open-source, MIT-licensed knowledge framework from Tencent built for enterprise-grade document understanding, semantic retrieval, and autonomous reasoning. It is organised around three capabilities: RAG-based quick Q&A for everyday lookups; a ReAct agent that orchestrates retrieval, MCP tools, a tenant skill catalog, session-persistent Docker, E2B or Cube sandboxes and web search to handle multi-step tasks; and a Wiki Mode in which agents distil raw documents into a self-maintaining, interlinked markdown knowledge base with an interactive knowledge graph, manual editing, revision history and one-click rollback. Knowledge curation is hands-on — a tree-structured folder view preserves the directory layout of uploads, and retrieval chunks can be edited, diffed and reverted like documents — while cross-session long-term memory retains user profile, preferences, facts and recurring interests. It ingests from Feishu Wiki and Drive, GitLab, Tencent IMA, Notion, Yuque, DingTalk Docs and RSS, handles over ten document formats including PDF, Word, Excel, images and XMind, and serves answers through IM channels such as WeCom, Feishu, Slack and Telegram. The modular architecture allows swapping LLMs, vector databases and storage backends across 20+ providers including OpenAI, DeepSeek, Qwen, Zhipu, Hunyuan, Gemini, MiniMax, NVIDIA, LiteLLM and Ollama, with full self-hosting for data sovereignty and Langfuse observability over agent reasoning, token usage and pipeline tracing.
Screenshots
Key Features
Use Cases

Frequently asked questions about WeKnora
What is WeKnora?
Tencent's open-source LLM knowledge framework turning documents into a RAG-queryable, agent-reasoned, self-maintaining wiki.
How does WeKnora work?
WeKnora works by combining RAG Quick Q&A: Semantic retrieval over ingested documents for everyday lookups, with editable retrieval chunks that support per-version diff, rollback and automatic reindexing., ReAct Agent Orchestration: An autonomous agent that plans across retrieval, MCP tools, a per-tenant skill catalog, sandboxes and web search to resolve complex multi-step questions., Wiki Mode: Agents distil raw uploads into a self-maintaining, interlinked markdown knowledge base with an interactive knowledge graph, in-browser editing, line-level diffs and one-click rollback., Skill Sandbox Runtime: Session-persistent Docker, E2B and Cube sandbox backends with per-tenant network policy, skill installation from ClawHub, SkillHub, git or zip, snapshots and live progress., Cross-Session Long-Term Memory: Profile, preference, fact, task and interest memory extracted automatically with user confirmation and searchable across sessions. to help users with Internal Knowledge Base: Turning scattered company documents into a queryable wiki that agents keep current instead of a folder of stale files., Data-Sovereign Deployment: Running a full RAG and agent stack on private cloud or local infrastructure where documents cannot leave the network., IM-Channel Support Bot: Serving grounded answers from company documents directly inside WeCom, Feishu, Slack or Telegram., Multi-Source Documentation Sync: Keeping a single searchable index over Notion, GitLab, Feishu and Yuque content that syncs automatically as sources change., Retrieval Quality Tuning: Editing, diffing and reverting individual retrieval chunks in the UI to fix bad answers without rebuilding the whole index..
What are the main features of WeKnora?
Key features include RAG Quick Q&A: Semantic retrieval over ingested documents for everyday lookups, with editable retrieval chunks that support per-version diff, rollback and automatic reindexing., ReAct Agent Orchestration: An autonomous agent that plans across retrieval, MCP tools, a per-tenant skill catalog, sandboxes and web search to resolve complex multi-step questions., Wiki Mode: Agents distil raw uploads into a self-maintaining, interlinked markdown knowledge base with an interactive knowledge graph, in-browser editing, line-level diffs and one-click rollback., Skill Sandbox Runtime: Session-persistent Docker, E2B and Cube sandbox backends with per-tenant network policy, skill installation from ClawHub, SkillHub, git or zip, snapshots and live progress., Cross-Session Long-Term Memory: Profile, preference, fact, task and interest memory extracted automatically with user confirmation and searchable across sessions..
Who is WeKnora for?
WeKnora is useful for anyone interested in Internal Knowledge Base: Turning scattered company documents into a queryable wiki that agents keep current instead of a folder of stale files., Data-Sovereign Deployment: Running a full RAG and agent stack on private cloud or local infrastructure where documents cannot leave the network., IM-Channel Support Bot: Serving grounded answers from company documents directly inside WeCom, Feishu, Slack or Telegram., Multi-Source Documentation Sync: Keeping a single searchable index over Notion, GitLab, Feishu and Yuque content that syncs automatically as sources change., Retrieval Quality Tuning: Editing, diffing and reverting individual retrieval chunks in the UI to fix bad answers without rebuilding the whole index..
How much does WeKnora cost?
WeKnora is free to use.
How do I get started with WeKnora?
Visit https://github.com/Tencent/WeKnora to sign up and explore WeKnora.
Explore more AI Ai Tools tools
Browse all Ai Tools tools →Compare WeKnora: vs Mise · vs BiBimba · vs VoiceCap · vs NM Signals