

Milliseconds.ai
AIA small decision model served over a REST API that returns typed labels, scores, spans, and JSON fields from text or images in milliseconds.
Milliseconds.ai
A small decision model served over a REST API that returns typed labels, scores, spans, and JSON fields from text or images in milliseconds.
About Milliseconds.ai
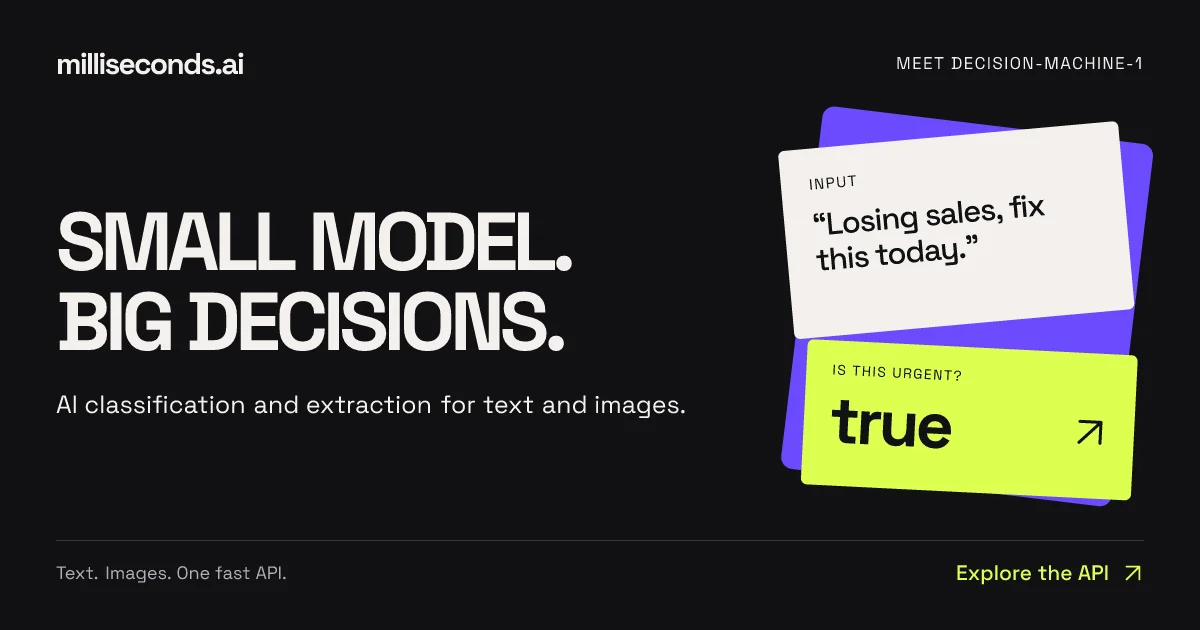
Milliseconds.ai is the API for decision-machine-1, a small model built to decide rather than generate. Instead of returning prose, every endpoint returns structured data an application can act on directly: a boolean with a probability, a label with per-class scores, a numeric rating, an answer span with source offsets, typed entities, or a JSON object matching a schema you supply. The API covers eight capabilities — yes-no, classify, classify-tree, rate, answer, extract, entities, and verify — over both text and images, and is reachable through REST, TypeScript and Python SDKs, and a dm1 CLI. Because the model is small, a decision comes back in roughly 90 milliseconds, with answer calls at 0.3–0.9 seconds and extraction at 2.5–3.5 seconds. Pricing is $0.04 per million input tokens with output tokens free, and test keys include 125 million free input tokens a month.
Screenshots
Key Features
Use Cases
Frequently asked questions about Milliseconds.ai
What is Milliseconds.ai?
A small decision model served over a REST API that returns typed labels, scores, spans, and JSON fields from text or images in milliseconds.
How does Milliseconds.ai work?
Milliseconds.ai works by combining Typed Decision Endpoints: Eight purpose-built routes — yes-no, classify, classify-tree, rate, answer, extract, entities, and verify — each returning structured JSON rather than free text, so application code can branch on the result immediately., Sub-Second Latency: A decision returns in about 90 milliseconds, answer calls in 0.3–0.9 seconds, and extraction in 2.5–3.5 seconds at medium detail, making the model usable inside request paths rather than background jobs., Calibrated Probabilities: Responses include per-label probabilities and a confidence value, so near-ties surface as uncertainty your application can route to a human instead of acting on silently., Schema-Driven Extraction: Send a JSON Schema and get back a filled object — up to five fields per extract call — ready for validation before writing to a record., Image Input: Send JPEG, PNG, or WebP images up to 5 MB as bytes, a data URL, or base64, billed as a fixed token count set by the detail level you request, with no image storage retained. to help users with Support Ticket Routing: Classifying inbound messages into billing, shipping, or technical queues and flagging urgent ones for faster response., Invoice and Receipt Processing: Extracting invoice number, vendor, total, and currency from document text or images into validated fields before writing a record., Content Moderation and Policy Checks: Verifying whether a return request, listing, or submission satisfies a written policy before it reaches a human reviewer., Sentiment and Priority Scoring: Rating customer frustration on a defined scale to sort a support queue by how badly each thread needs attention., Entity Recognition in Records: Pulling people, organizations, claim IDs, and dates out of free-text notes for search and record matching..
What are the main features of Milliseconds.ai?
Key features include Typed Decision Endpoints: Eight purpose-built routes — yes-no, classify, classify-tree, rate, answer, extract, entities, and verify — each returning structured JSON rather than free text, so application code can branch on the result immediately., Sub-Second Latency: A decision returns in about 90 milliseconds, answer calls in 0.3–0.9 seconds, and extraction in 2.5–3.5 seconds at medium detail, making the model usable inside request paths rather than background jobs., Calibrated Probabilities: Responses include per-label probabilities and a confidence value, so near-ties surface as uncertainty your application can route to a human instead of acting on silently., Schema-Driven Extraction: Send a JSON Schema and get back a filled object — up to five fields per extract call — ready for validation before writing to a record., Image Input: Send JPEG, PNG, or WebP images up to 5 MB as bytes, a data URL, or base64, billed as a fixed token count set by the detail level you request, with no image storage retained..
Who is Milliseconds.ai for?
Milliseconds.ai is useful for anyone interested in Support Ticket Routing: Classifying inbound messages into billing, shipping, or technical queues and flagging urgent ones for faster response., Invoice and Receipt Processing: Extracting invoice number, vendor, total, and currency from document text or images into validated fields before writing a record., Content Moderation and Policy Checks: Verifying whether a return request, listing, or submission satisfies a written policy before it reaches a human reviewer., Sentiment and Priority Scoring: Rating customer frustration on a defined scale to sort a support queue by how badly each thread needs attention., Entity Recognition in Records: Pulling people, organizations, claim IDs, and dates out of free-text notes for search and record matching..
How much does Milliseconds.ai cost?
Milliseconds.ai offers a free tier with paid plans for advanced features.
How do I get started with Milliseconds.ai?
Visit https://www.milliseconds.ai/ to sign up and explore Milliseconds.ai.
Explore more AI Ai Models tools
Browse all Ai Models tools →Compare Milliseconds.ai: vs SWE-2 · vs Desert Ant Labs · vs Hy4 preview · vs Soup CLI